LOCAL LLM FIELD GUIDE
TensorFold is the Zig server that serves models on Metal and CUDA
TensorFold is Ash Hart's inference engine, Apache-2.0, at github.com/ashhart/TensorFold. A Zig binary reads the checkpoint, tokenizes the request, and runs Metal or CUDA kernels directly. The serve path in the README does not need a Python or MLX install. The Linux quick start read on 2026-11-12 pins release 1.2.7. The changelog points at the 1.0.0 notes for the native binary's model list and for migration off older recipes.
NATIVE ZIG SERVER
The binary reads the checkpoint and serves it
- Check the release table first. No row means the release binary does not serve it
- Listen on 127.0.0.1 until you mean to expose a port
- Compare tokens with drafts off on the same engine
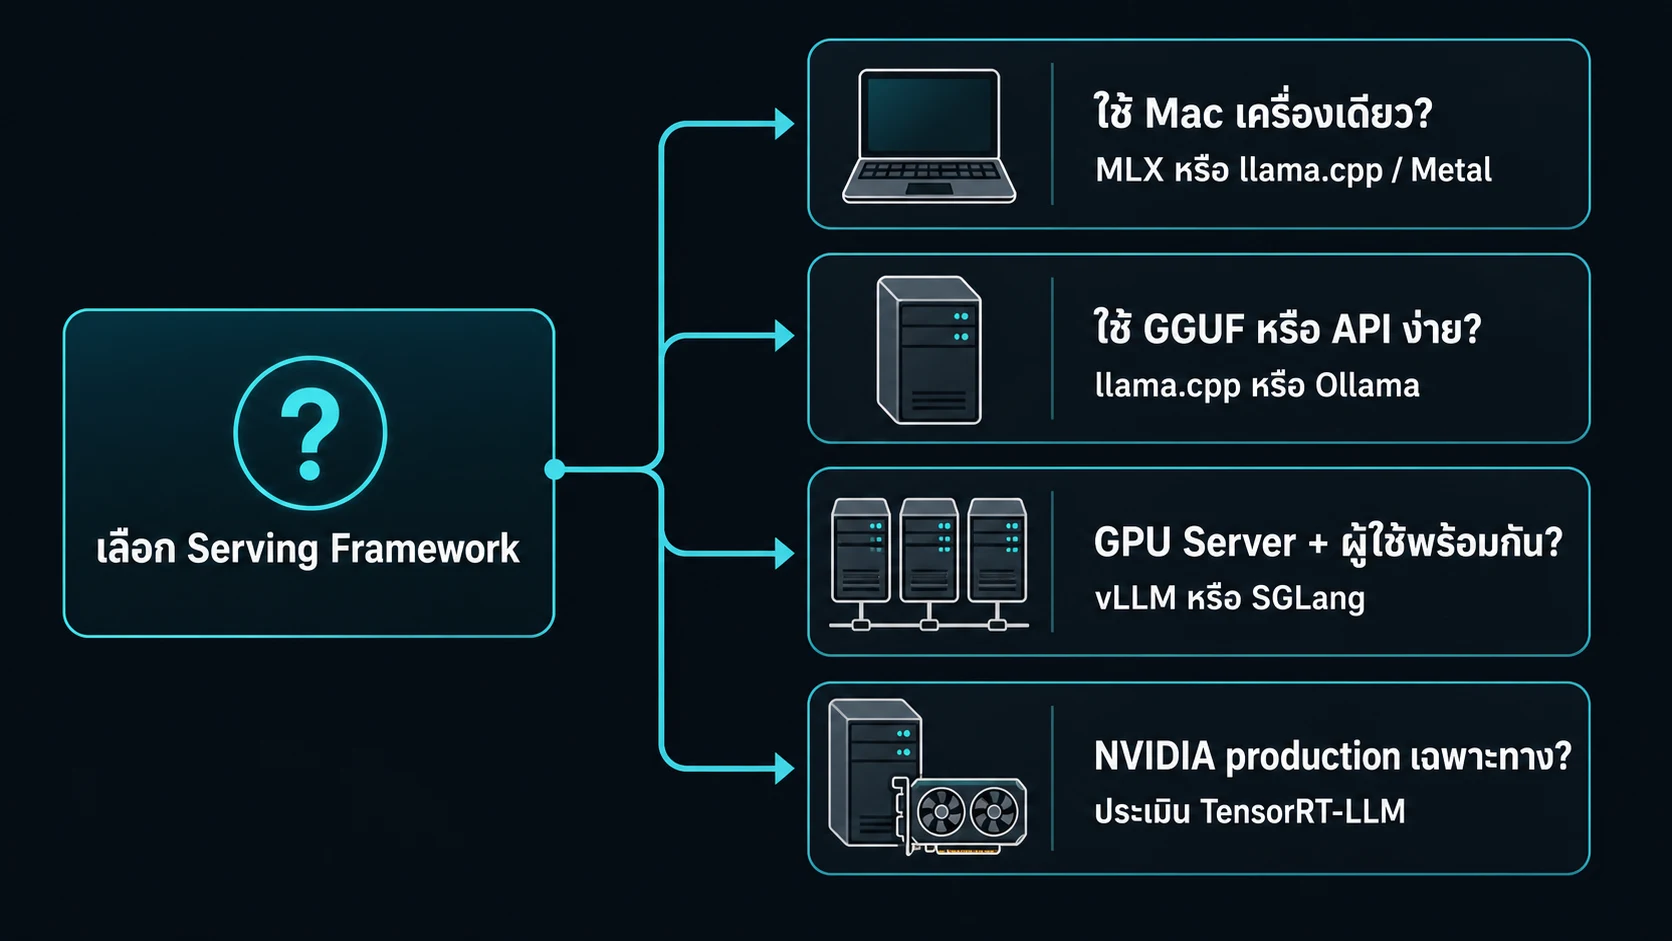
USE IT ON REAL WORK
Pick a TensorFold path from the release table
Start from a row in the README model table. If the row is missing, the release binary does not serve that checkpoint.
A community recipe that pins a fork can add a model, and its speed table and token contract belong to the branch the recipe names.
| Path | Use it when | Write down |
|---|---|---|
| Native release | The model has a README table row | The binary version, such as 1.2.7, and the pinned pull command |
| Mac | The row says Metal or MLX | How many machines, because some models need two |
| NVIDIA | The row says CUDA and names a checked chip | Driver R580 or newer for the current archive |
| DeepSeek on two Sparks | You use the Mia recipe that pins a fork | Zig 0.17.0, branch deepseek-v41-zig, 196 GiB pack |
| Quoting tok/s | The table publishes its conditions | Clock, context, streams, temperature, and draft state |
Before starting the server
- Confirm the model is in the release table or in a recipe that names its fork
- Listen on 127.0.0.1 until you mean to expose a port, and set a key if you do
- Record the draft state, because equal tokens are compared with drafts off on the same engine
- Do not replace the calculator roofline with the Mia recipe's tok/s
- For DeepSeek, keep the Engram tables on local disk for every rank
tensorfold serve REPO --host 127.0.0.1 --port 8080 --context 8192 --no-thinkingWhat the binary does itself
On a Mac the install line is the Homebrew formula ashhart/tensorfold/tensorfold. On Linux you unpack the release archive, linux-aarch64 on a GB10 and linux-x86_64 on an x86_64 host. It wants glibc 2.28 or newer and an NVIDIA driver at R580 or newer, because the kernels are built with CUDA 13. On Windows with an NVIDIA GPU the README points at a separate native build guide.
The server listens on 127.0.0.1 port 8080 by default. It serves chat, completions, the Responses API, and Anthropic Messages. --name sets the model id clients see. The docs also describe TensorFold Web and an Apple Silicon desktop app, and that app launches the bundled tensorfold-native binary.
Some recipe pages still describe the older Python 0.6.6 engine. The README says to use the native section of such a recipe together with the current changelog. The release serve path is the binary, not a full Python stack.
What exact decoding promises
The Exact decoding section says every accepted draft token must equal the token the same native engine would produce with drafts off. A resumed request must equal a fresh run, and each concurrent stream must equal its solo run. The comparison fixes the checkpoint, the backend, the settings, and the runtime.
Different quantizations and different backends can produce different outputs. The contract does not say an EXL3 file matches BF16 bit for bit, and it does not say Metal and CUDA emit the same tokens for two different formats. --no-drafts is how you ask the same engine for the plain reference.
Documented drafters include an in-checkpoint MTP head and an external drafter passed with --drafter, such as the DFlash2 drafter for Qwen3.8-27B. Without a drafter, a model that needs an external one decodes plain.
The release table is the boundary
The README table lists the native release's serving paths, with tensorfold pull commands and a machine scope. Rows that matter for hardware in this calculator include Qwen3.8-27B MLX 4-bit with its DFlash2 drafter, Qwen3.8 Flash Next on MLX and on CUDA, Nemotron 3.5 Lightning as MLX 4-bit and as NVFP4, GLM-5.3-Flash MLX on two M5 Ultras, GLM-5.3-Flash NVFP4, FP4-Local, and EXL3/TR3 on CUDA, plus Qwen3.6-35B-A3B and Gemma 4.
That table marks GLM-5.3-Flash EXL3/TR3 as an experimental checkpoint and tells you to use the native rank options, not the Python install. A few rows record HIP evidence for one model, such as dots.mocr on one checked Radeon. Those rows do not put every model in the table on AMD.
The line to read before planning DeepSeek is the README statement that DeepSeek checkpoints are not served by any release binary, and that whole-model gate 827 is still open. The changelog shows DeepSeek-V4.1 kernel work landing in the tree, including spots where serving still refuses some rank shapes. In-tree work and a row in the release table are different states.
The two-Spark DeepSeek recipe pins a fork
MiaAI-Lab/DeepSeek-v4.1-Flash-1017-2x-DGX-Sparks does not point the stock release command tensorfold serve at the official DeepSeek checkpoint. Its README says the engine is TensorFold native at Zig 0.17.0, BertholomusAI's dsv41 family at TP=2, pinned to the bertholomus/TensorFold branch deepseek-v41-zig plus that recipe's patches. The credits on that page separate Ash Hart and the TensorFold contributors from Albert Lee's DeepSeek port.
The weights are Mia-AiLab/DeepSeek-V4.1-Flash-1017-EXL3-EAQ-v1-2.9-bpw at 196 GiB. The served model id is DeepSeek-V4.1-Flash-1017 on port 8888, with image input, tool calling, thinking, and DSpark from the checkpoint draft blocks. The recipe's default HOST is 0.0.0.0, so the API is open on the network until you set a key or change the bind. The serving guide on this site starts from 127.0.0.1 until there is a reason to expose a port.
Two 128 GB Sparks linked by ConnectX-7 are the hardware boundary of this recipe. GLM-5.3-Flash and Qwen3.8 Flash Next have their own Mia TensorFold recipes. Flags from the DeepSeek recipe do not automatically apply to every family in the release table.
Read 80.7 tok/s as one measured run
The table in the recipe README, as read for this page, comes from sparkDash on one pair. Both GPUs were capped at 2,200 MHz, CONTEXT was 524288, drafts were on, and the head was also running a desktop and about 18 small containers. One stream measured 80.7 tok/s for prose at temperature 0 with thinking off, 63.9 tok/s for prose at temperature 0.7 with thinking on, and 118.1 tok/s for code at temperature 0 with thinking off, with TTFT of 133 ms, 214 ms, and 213 ms.
Prefill stays near 2,100 tok/s from about 4K to about 256K tokens when the Engram tables are on local disk on both machines. The reported points are 2,105.9 tok/s at 4,114 tokens and 2,065.0 tok/s at 262,163 tokens. The same report says prefill falls to about 690 to 890 tok/s when those tables are read over NFS.
Important note: this page does not promote those rates into a general TensorFold speed against vLLM or mlx_lm. The TensorFold README does not publish that comparison on the same prompt, the same clock, and the same draft state.
How this relates to the calculator
The llm-cal calculator estimates tok/s from bandwidth and from framework, quantization, and speculative-decoding factors. That number is a roofline for ranking options. The 80.7 tok/s table is a separate measurement on one Spark pair. When a TensorFold or EXL3 result card shows a speed, read it as the catalog estimate, then open the checkpoint's own README if you need the publisher's measurement.
Before comparing two paths, lock the model, the weight format, the context, the stream count, the temperature, the draft state, and the GPU clock cap. If one path is release binary 1.2.7 and the other is the fork the DeepSeek recipe pins, write the branch and revision into the lab notes. The equal-token contract is tied to one engine.
Frequently asked questions
Does TensorFold serving need Python installed?
The serve path in the current README is a Zig binary that reads the checkpoint, tokenizes, and runs Metal or CUDA kernels itself. The Linux example pins release 1.2.7. Older recipes may still describe the Python 0.6.6 engine, but the release install does not put Python or MLX on the serve path.
Does a TensorFold release binary serve DeepSeek-V4.1?
The README read on 2026-11-12 says no release binary serves DeepSeek checkpoints yet, and gate 827 is still open. Mia's two-Spark recipe pins BertholomusAI's deepseek-v41-zig fork plus that recipe's patches, on Zig 0.17.0. That is a different binary from the release tensorfold serve command.
Sources
Try your configuration
Put the intended model, quantization, context, framework, and hardware into the calculator, then validate with a production-like benchmark.
Open calculator