LOCAL LLM FIELD GUIDE
VRAM Management for Large MoE Models on Multi-GPU Clusters
Mixture-of-Experts (MoE) models like DeepSeek-V3/R1 (671B Total / 37B Active) operate like a room with 256 specialists and a receptionist routing each word to the 8 most relevant experts. Even though compute ops require only 37B active parameters, total VRAM must store all 671B weights. Expert Parallelism (EP), Tensor Parallelism (TP), and Multi-Head Latent Attention (MLA) are essential for cluster efficiency.
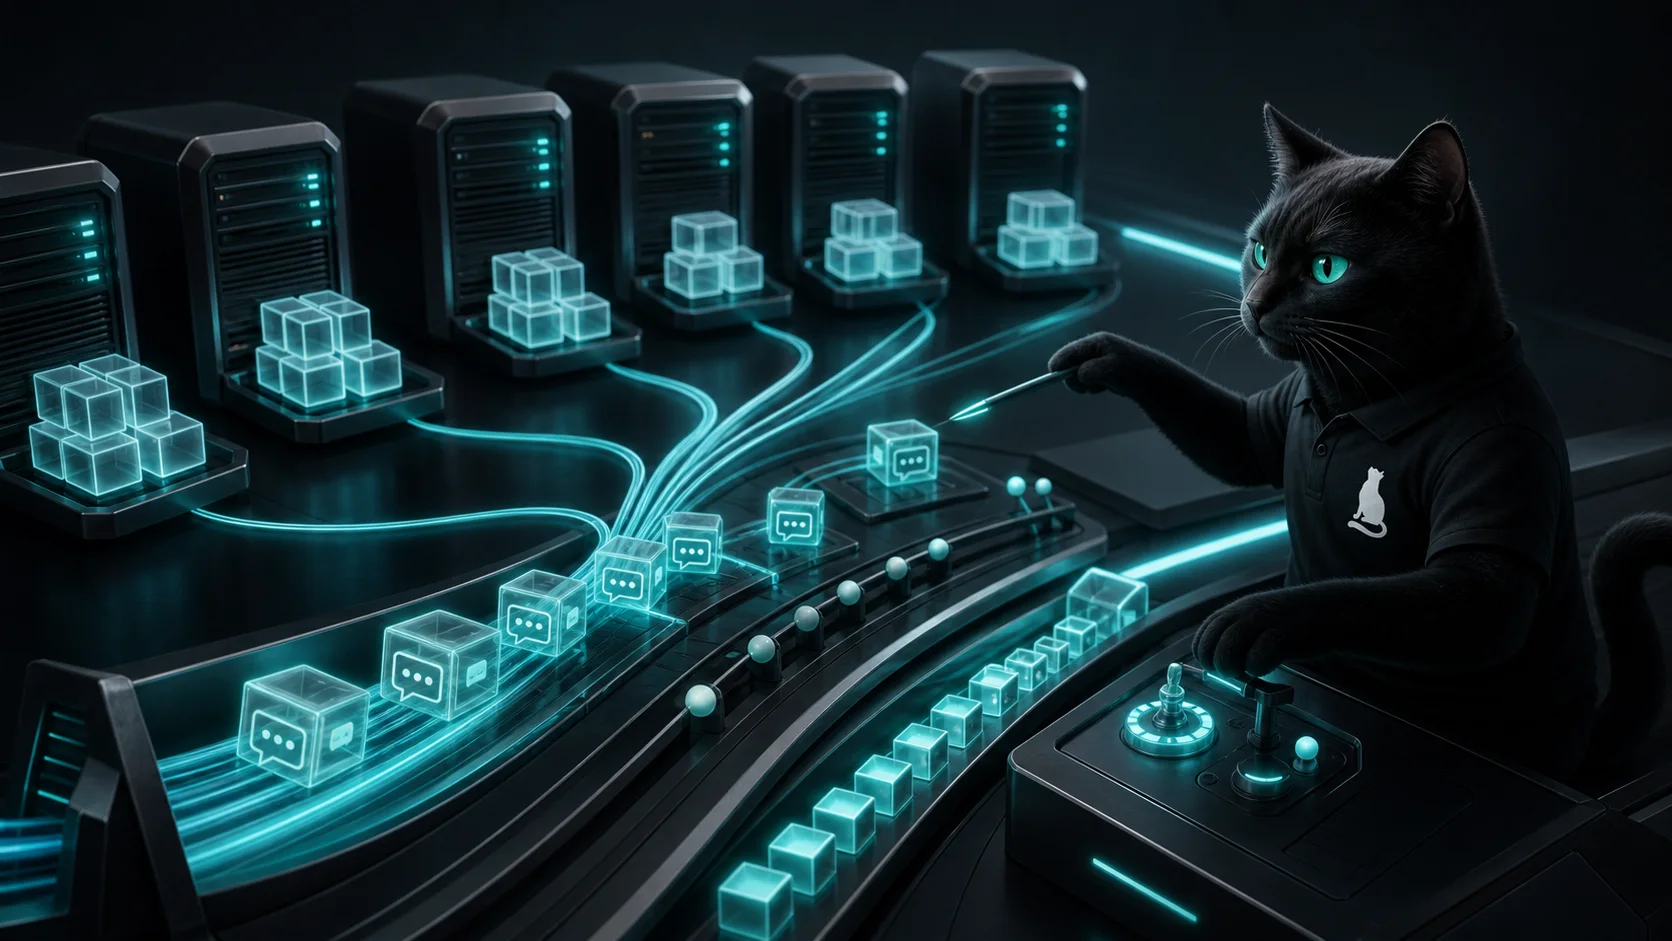
MIXTURE OF EXPERTS
671B Total Parameters in VRAM 37B Active per token
- VRAM Footprint
- Must reserve all 671B total weights across cluster
- Compute Speed
- Runs at speed of 37B active parameters
USE IT ON REAL WORK
Plan VRAM and Multi-GPU for MoE Models
Start from Total Parameters (671B) to reserve VRAM, and Active Parameters (37B) to estimate compute speed.
Use Expert Parallelism (EP) to distribute experts across GPUs over NVLink, and use FP8 KV cache to save memory.
| Factor | Recommendation | Caution |
|---|---|---|
| Model Weights (671B) | Budget memory for 671B, not 37B (~670 GB at FP8) | Server fails to boot if total VRAM is insufficient |
| Multi-GPU Interconnect | Use NVLink for Expert Parallelism (EP) | PCIe cards without NVLink hit All-to-All routing bottlenecks |
| KV Cache Architecture | DeepSeek MLA slashes KV cache memory >90% | KV footprint still scales under high concurrency |
| Expert Offloading | Offload non-critical experts to CPU/NVMe | Enables running on smaller GPUs but reduces decode tok/s |
MoE Cluster Deployment Checklist
- Ensure aggregate GPU VRAM exceeds Total Weights + KV Overhead
- Verify NVLink / NVSwitch or InfiniBand drivers between GPUs
- Select a runtime with native EP and MLA support such as vLLM or SGLang
- Test FP8 E4M3 weights with FP8 KV cache before testing 4-bit quants
vllm serve deepseek-ai/DeepSeek-V3 \
  --tensor-parallel-size 1 \
  --pipeline-parallel-size 1 \
  --expert-parallel-size 8 \
  --kv-cache-dtype fp8 \
  --max-model-len 32768
Active vs Total Parameters in VRAM Budget
MoE models like DeepSeek-V3 feature 671B total parameters, but route tokens to only 8 active experts plus 1 shared expert (37B active). Crucially, 37B active parameters does NOT mean a 37B model VRAM footprint. All 256 experts (671B) must stay resident in GPU memory (~670 GB at FP8 precision). Decode throughput scales like a 37B model, but weight footprint requires full 671B capacity.
Multi-GPU Parallelism: EP, TP, and PP
Serving large MoE models across GPUs relies on three key parallelism strategies:
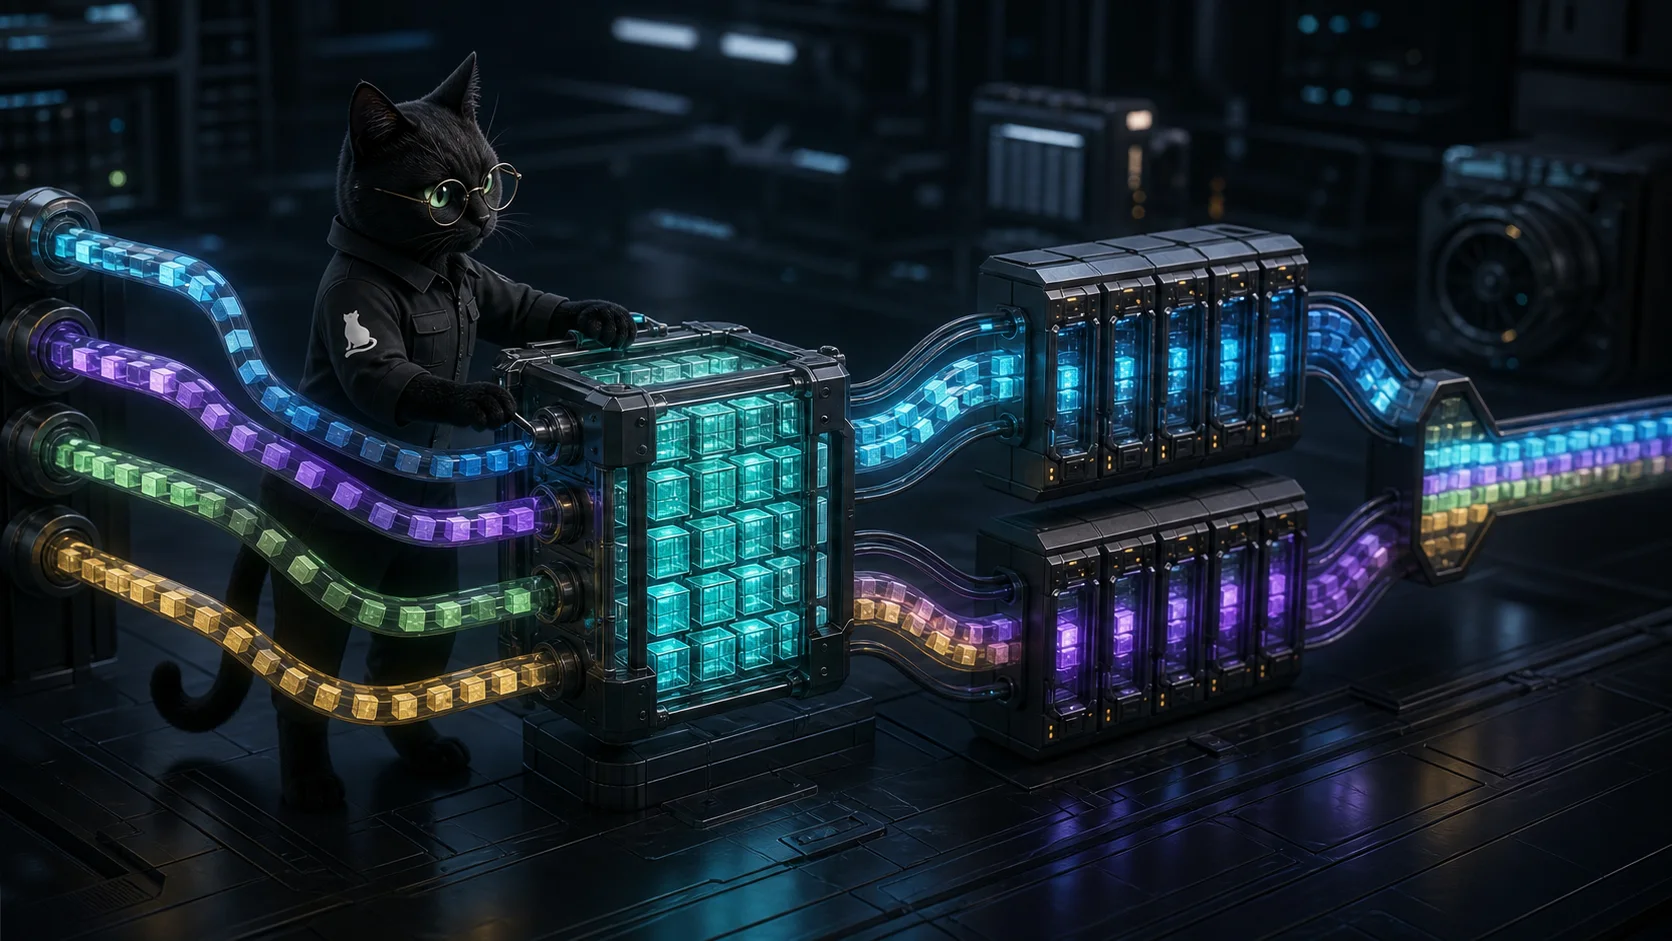
- Expert Parallelism (EP): Distributes experts across GPUs (e.g. GPU#1 holds Experts 1-32, GPU#2 holds 33-64). EP minimizes weight duplication but creates All-to-All communication bottlenecks during token routing, requiring NVLink.
- Tensor Parallelism (TP): Splits individual matrix layers for shared experts and attention.
- Pipeline Parallelism (PP): Distributes model layers depth-wise across nodes connected via InfiniBand/RoCE.
MLA (Multi-Head Latent Attention) Slashes KV Cache
DeepSeek-V3/R1 uses Multi-Head Latent Attention (MLA), compressing Key-Value states into a 576-dim latent vector per token. This reduces KV Cache memory by over 90%, enabling 64K-128K context windows and high concurrency without hitting OOM.
MoE Expert Quantization Caveats
Quantizing MoE models requires care:
- FP8 (E4M3): The primary baseline for DeepSeek-V3/R1, maintaining near-lossless precision on H100/B200/RTX 4090 Tensor Cores.
- 4-bit (AWQ / IQ4_XS): Reduces model footprint to ~350 GB, enabling deployment on 8x RTX 4090 / 3090 nodes with offloading. Beware of router drift where low-precision routers misroute tokens.
Hardware Cluster Configurations
- Enterprise Production Cluster (8x H100 / H200): FP8 native with EP=8 over NVLink for maximum throughput.
- Workstation / Budget Cluster (8x RTX 4090 24GB or Mac Cluster): 4-bit quantization with CPU/NVMe expert offload via vLLM or SGLang.
Sources
Try your configuration
Put the intended model, quantization, context, framework, and hardware into the calculator, then validate with a production-like benchmark.
Open calculator